

AMD Ryzen 9
Define Pro
1× RTX PRO 4000 · 24GB
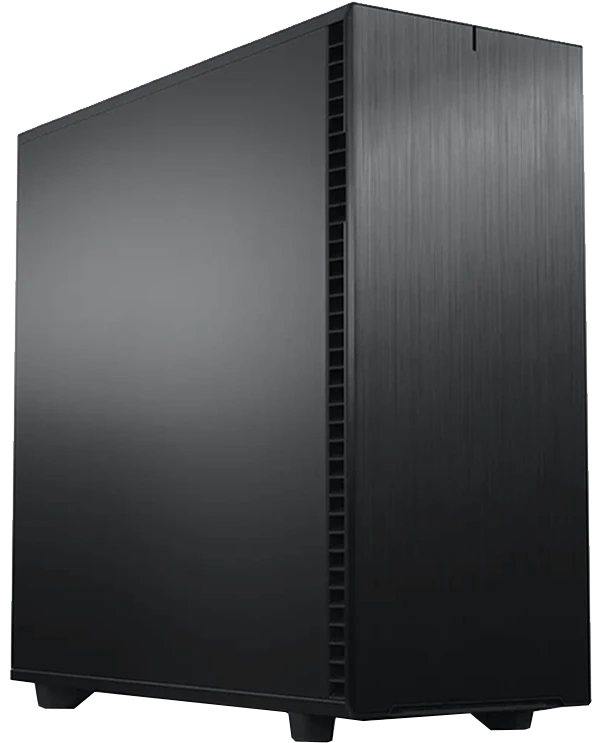
 Ryzen 9 9950X · 16 cores
 1× RTX PRO 4000 · 24GB
 64GB DDR5
Starting at$6,980
Ships in an estimated 5 to 10 business daysLifetime support
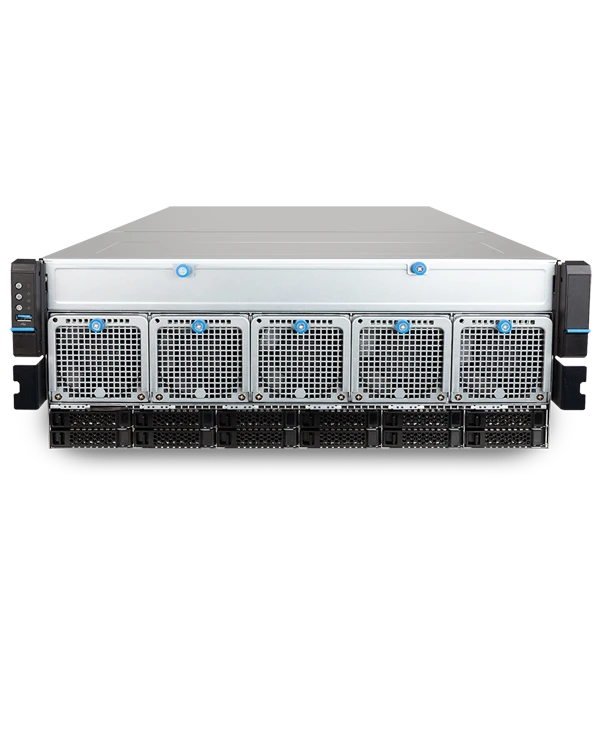
AI workstations and GPU servers for deep learning, with up to four RTX PRO 6000 or H200 NVL GPUs, configured for what you run and ready to work the day they arrive.
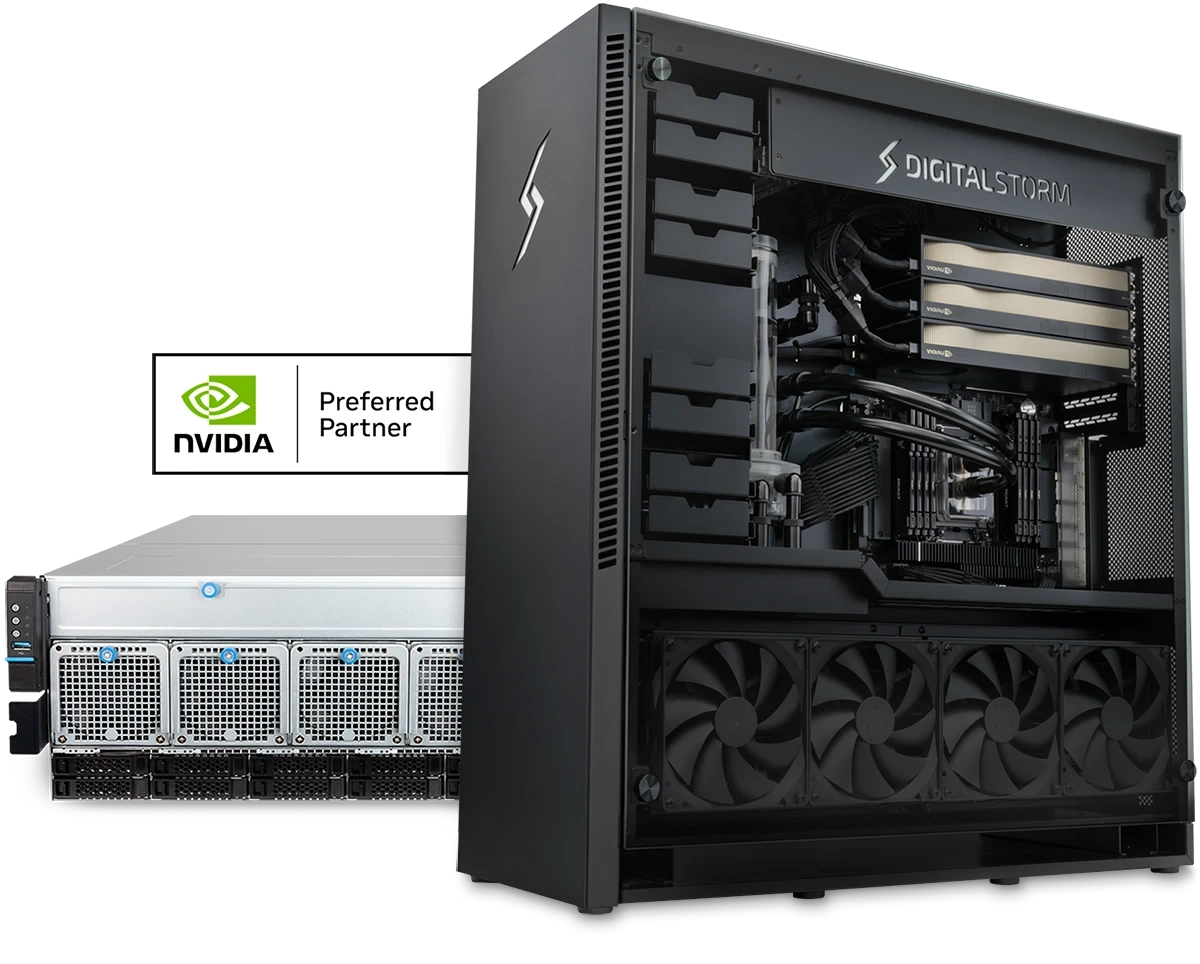
We install Ubuntu, the NVIDIA driver, CUDA, cuDNN and the frameworks you name before it ships. Your quote lists every version.
 PyTorch
 TensorFlow
 Keras
 JupyterLab
 Docker
 CUDA · cuDNN
 Ollama
 vLLM
 Hugging FaceComfyUI
Not a parts list: a model answering locally, a notebook session and a training run, recorded on our own machines.
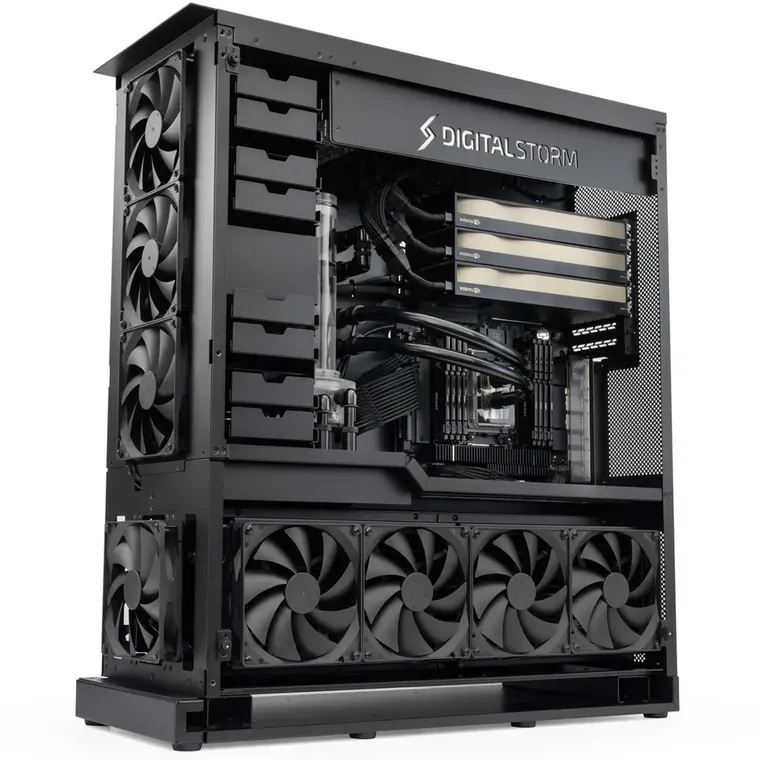
A job that runs for three days asks more of a machine than a benchmark does. That is what the configuration is designed around.
Digital Storm has built high-performance systems in California since 2002, and today builds AI workstations and GPU servers for startups, university labs and enterprise research teams.


Inference, fine-tuning, full training or data science: see the memory estimate, the assumptions behind it and every system that holds it.
Two ways in, both ending at a system you can price.
Not sure? Ask an engineer ›
Start with what you do, then the model, job and precision. The estimate updates as you go.
42GB of weights at Q4, plus 20% for KV cache and overhead. An estimate: it assumes a short context and batch 1. Long contexts and bigger batches need more.
Every system we build for this work, sorted by price. The lowest-cost one that holds your estimate is marked. Customize and buy any of them online, or ask for a quote and an engineer confirms the details.
Ryzen 9 9950X · 16 cores1× RTX PRO 4000 · 24GB64GB DDR5Core Ultra 9 285K · 24 cores1× RTX PRO 4000 · 24GB64GB DDR5Ryzen 9 9950X · 16 cores1× RTX PRO 4500 · 32GB64GB DDR5Core Ultra 9 285K · 24 cores1× RTX PRO 4500 · 32GB64GB DDR5Ryzen 9 9950X · 16 cores1× RTX 5090 · 32GB64GB DDR5Core Ultra 9 285K · 24 cores1× RTX 5090 · 32GB64GB DDR5Core Ultra 9 285K · 24 cores1× RTX PRO 5000 48GB64GB DDR5Ryzen 9 9950X · 16 cores1× RTX PRO 5000 48GB64GB DDR5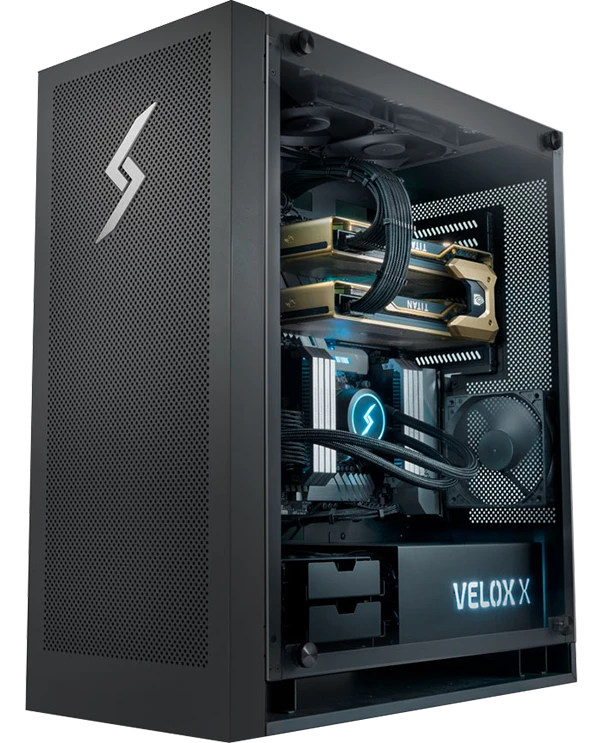 Threadripper 9960X · 24 cores1× RTX PRO 4000 · 24GB128GB DDR5 ECCThreadripper 9960X · 24 cores1× RTX PRO 4500 · 32GB128GB DDR5 ECCThreadripper PRO 9965WX · 24 cores1× RTX PRO 4000 · 24GB128GB DDR5 ECCXeon w7-3565X · 32 cores1× RTX PRO 4000 · 24GB128GB DDR5 ECCThreadripper 9960X · 24 cores1× RTX 5090 · 32GB128GB DDR5 ECCRyzen 9 9950X · 16 cores1× RTX PRO 5000 72GB64GB DDR5Core Ultra 9 285K · 24 cores1× RTX PRO 5000 72GB64GB DDR5Threadripper PRO 9965WX · 24 cores1× RTX PRO 4500 · 32GB128GB DDR5 ECCXeon w7-3565X · 32 cores1× RTX PRO 4500 · 32GB128GB DDR5 ECCThreadripper PRO 9965WX · 24 cores1× RTX 5090 · 32GB128GB DDR5 ECCXeon w7-3565X · 32 cores1× RTX 5090 · 32GB128GB DDR5 ECCThreadripper 9960X · 24 cores1× RTX PRO 5000 48GB128GB DDR5 ECCCore Ultra 9 285K · 24 cores1× RTX PRO 6000 · 96GB64GB DDR5Threadripper PRO 9965WX · 24 cores1× RTX PRO 5000 48GB128GB DDR5 ECCXeon w7-3565X · 32 cores1× RTX PRO 5000 48GB128GB DDR5 ECCThreadripper 9960X · 24 cores1× RTX PRO 5000 72GB128GB DDR5 ECCThreadripper PRO 9965WX · 24 cores1× RTX PRO 5000 72GB128GB DDR5 ECCRyzen 9 9950X · 16 cores1× RTX PRO 6000 · 96GB192GB DDR5Xeon w7-3565X · 32 cores1× RTX PRO 5000 72GB128GB DDR5 ECCThreadripper 9960X · 24 cores2× RTX 5090 · 32GB256GB DDR5 ECCThreadripper PRO 9965WX · 24 cores2× RTX 5090 · 32GB256GB DDR5 ECCThreadripper PRO 9965WX · 24 cores1× RTX PRO 6000 · 96GB128GB DDR5 ECCXeon w7-3565X · 32 cores2× RTX 5090 · 32GB256GB DDR5 ECCXeon w7-3565X · 32 cores1× RTX PRO 6000 · 96GB128GB DDR5 ECCThreadripper 9960X · 24 cores1× RTX PRO 6000 · 96GB256GB DDR5 ECCThreadripper 9960X · 24 cores2× RTX PRO 5000 48GB256GB DDR5 ECCThreadripper PRO 9965WX · 24 cores2× RTX PRO 5000 48GB256GB DDR5 ECCXeon w7-3565X · 32 cores2× RTX PRO 5000 48GB256GB DDR5 ECCThreadripper 9960X · 24 cores2× RTX PRO 5000 72GB256GB DDR5 ECCThreadripper PRO 9965WX · 24 cores2× RTX PRO 5000 72GB256GB DDR5 ECCXeon w7-3565X · 32 cores2× RTX PRO 5000 72GB256GB DDR5 ECCThreadripper 9960X · 24 cores2× RTX PRO 6000 · 96GB256GB DDR5 ECCThreadripper PRO 9965WX · 24 cores2× RTX PRO 6000 · 96GB256GB DDR5 ECCXeon w7-3565X · 32 cores2× RTX PRO 6000 · 96GB256GB DDR5 ECC
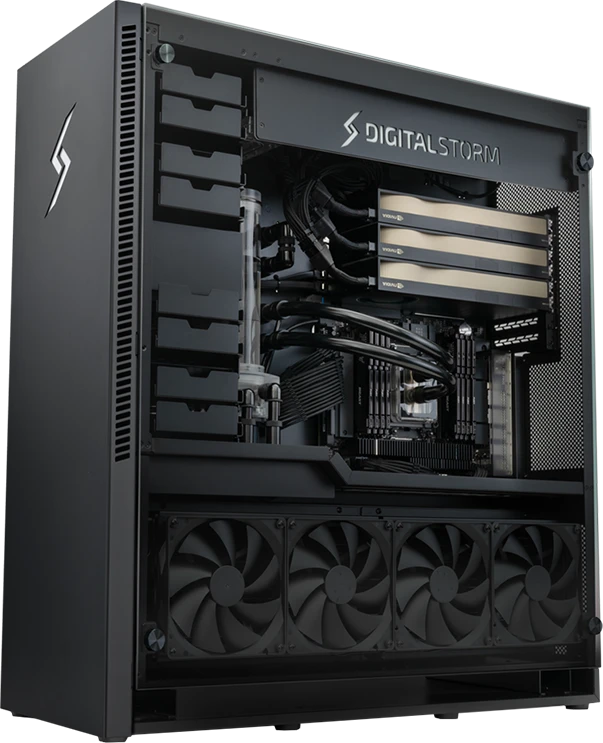 Threadripper PRO 9965WX · 24 cores4× RTX PRO 5000 48GB512GB DDR5 ECCXeon w7-3565X · 32 cores4× RTX PRO 5000 48GB512GB DDR5 ECCThreadripper PRO 9965WX · 24 cores4× RTX PRO 5000 72GB512GB DDR5 ECCXeon w7-3565X · 32 cores4× RTX PRO 5000 72GB512GB DDR5 ECCThreadripper PRO 9965WX · 24 cores4× RTX PRO 6000 · 96GB512GB DDR5 ECCXeon w7-3565X · 32 cores4× RTX PRO 6000 · 96GB512GB DDR5 ECC

Your AI systems engineer
Talk through your models, your runtime and what the machine has to hold. You get the configuration we recommend, and where a cheaper card would serve your models just as well.
Memory decides how much context a card can hold on a large model. Multi-card RTX PRO 6000 towers use the 300 W Max-Q edition, which keeps 93% or more of the generation speed at half the power.
Both are two-card Threadripper towers. The difference is what one card holds.
Memory from this page’s rule: 4-bit weights plus 20% for cache and overhead, at a short context and batch 1. The speed figures above are single-card runs; we have not found a published two-card run for these exact cards.
If your models fit in 32 GB a card, the 5090 pair is the sensible buy. If one model has to sit on one card, or an LLM and an image pipeline run at once, the PRO pair holds it.
Buying one card now and a second next year? Say so. We explain the expansion options in the platform you choose, and the quote says what adding the second card will need.
Tell us what you run. A systems engineer replies with a configuration and pricing in one business day.
DIY fits when you have the hours to integrate and support it. Cloud fits when usage is bursty or needs cluster scale on demand. An OEM tower fits when IT mandates a fleet vendor. Here is how the four compare for the rest.
| Capability | Digital StormThat’s us | DIY build | Cloud GPUs | OEM (Dell/HP) |
|---|---|---|---|---|
| Cost structure | Purchase price | Parts + your time | Ongoing usage | Purchase price |
| Your data and weights stay in-house | ✓ | ✓ | Per contract | ✓ |
| Sized to your models and VRAM math | ✓ | Your math | Instance sizes | Catalog options |
| Multi-GPU and rackmount builds | ✓ | You integrate | ✓ | Catalog options |
| 72-hour full-load burn-in before shipping | ✓ | – | n/a | Factory QA |
| An engineer on your quote, lifetime support | ✓ | – | Support plans | Contracts |
| Formal quotes, PO, net terms | ✓ | – | ✓ | ✓ |
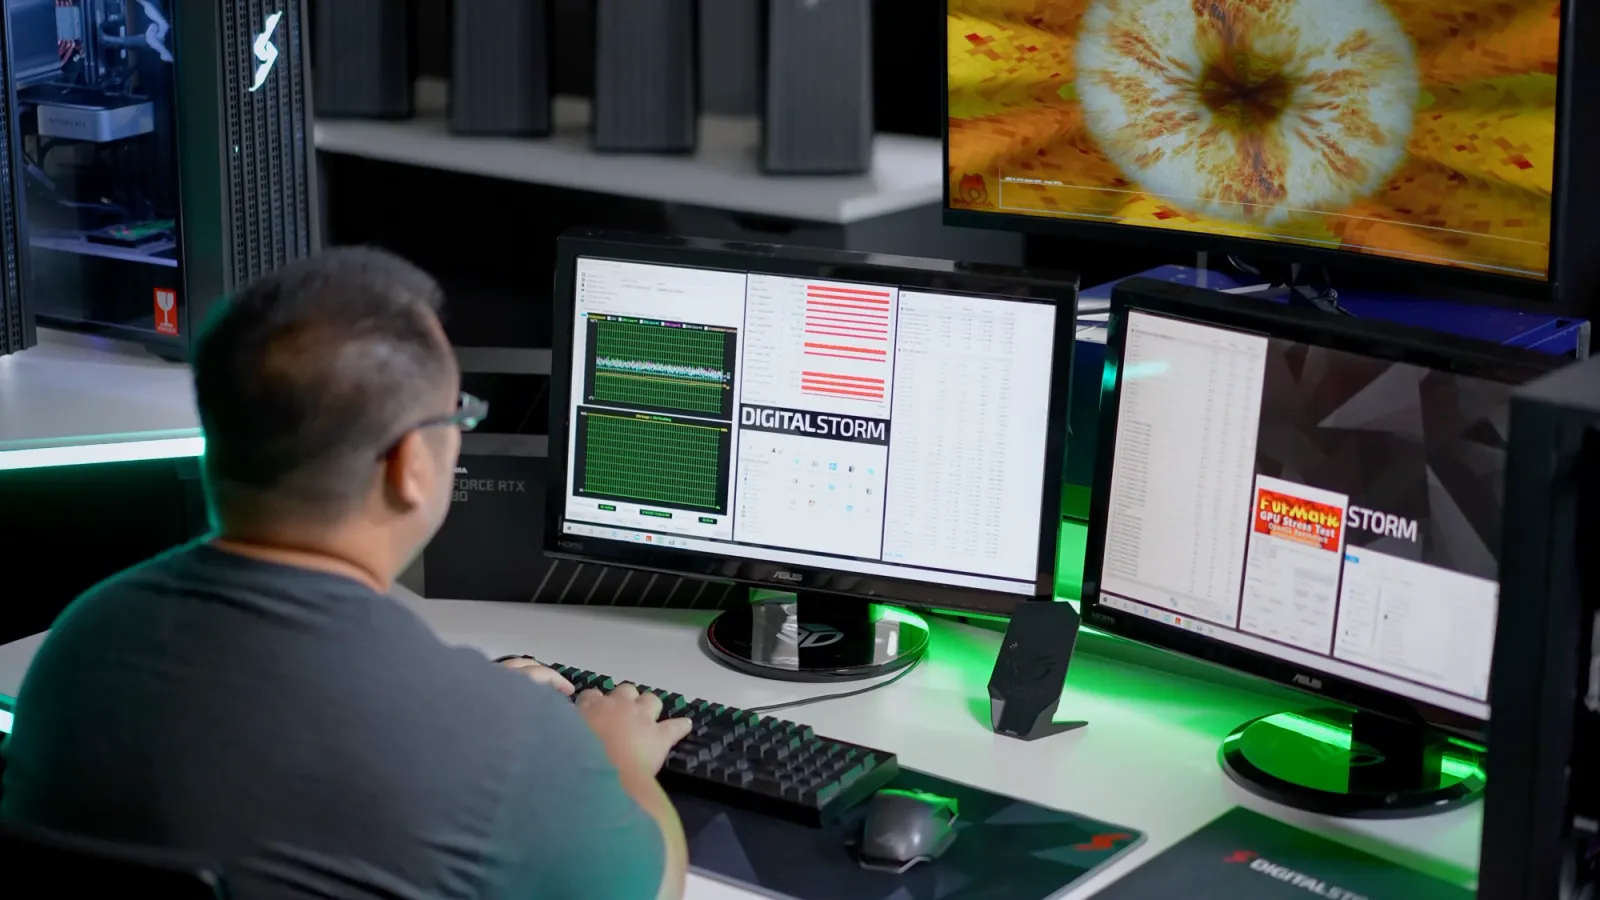
The failure modes that burn ML teams, and what we build differently to avoid them.
Send your workload and get a configuration with itemized pricing in one business day. No obligation.
Purchase orders welcome, tax-exempt for eligible organizations · Call an engineer at 1-669-235-3810

We use cookies and similar technologies to enhance your browsing experience and analyze website traffic. By continuing to use this website, you consent to our use of cookies as described in our Privacy Policy. Click here to opt out of data sharing.