NVIDIA Preferred PartnerBuilt in California · 24+ yearsPurchase orders welcomeTalk to an engineer· 1-669-235-3810My accountCartSupport
AI, inference & research computing

Get the GPU server your team actually needs.

GPU servers and AI servers for a lab or a team that shares one machine, with two to four RTX PRO 6000 or H200 NVL GPUs, sized to who runs what and ready to work the day they arrive.
  • 24+ yearscustom systems
  • NVIDIAPreferred Partner
  • 72-hour burn-inbefore it ships
  • Lifetime supportUS-based team
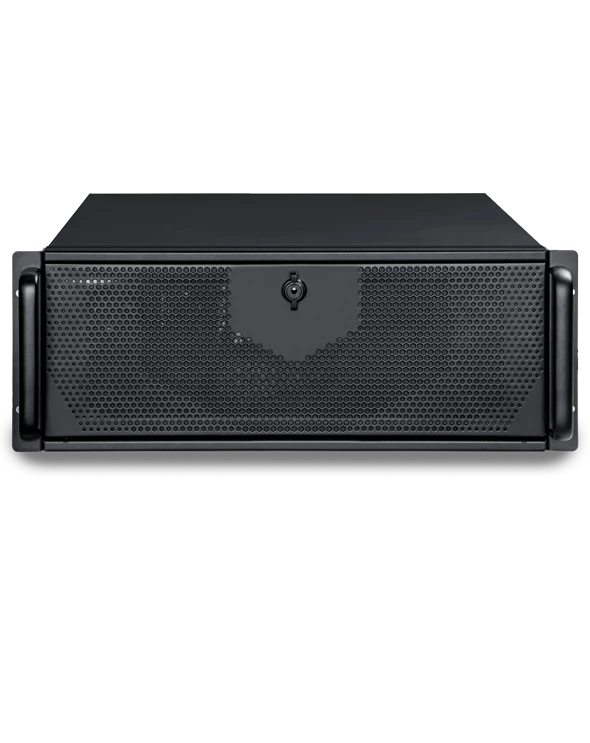
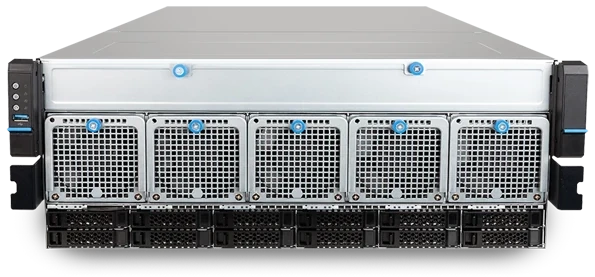
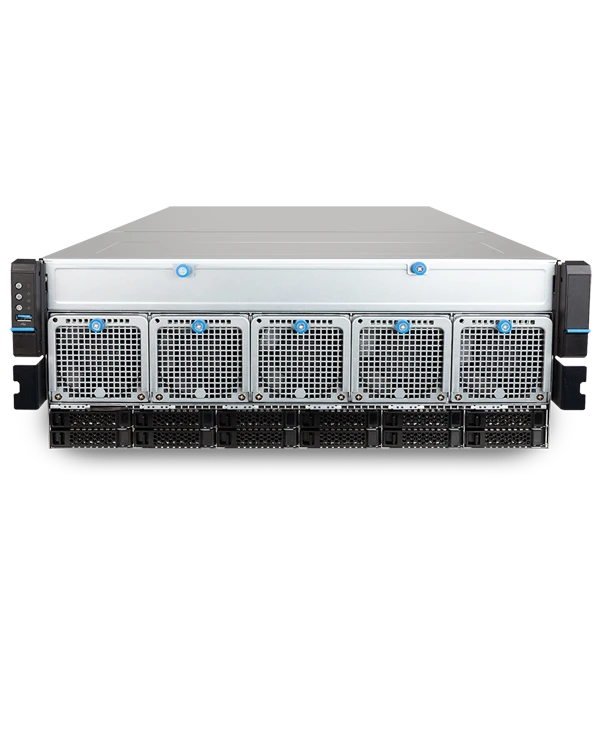
Digital Storm Server Pro rackmount GPU server
Start with your software in place.

We install Ubuntu, the NVIDIA driver, CUDA, cuDNN and the frameworks you name before it ships. Your quote lists every version.

PyTorchTensorFlowKerasJupyterLabDockerCUDA · cuDNNOllamavLLMHugging FaceComfyUI

Trusted by research labs and enterprise AI teams

Digital Storm has built high-performance systems in California since 2002, and today builds AI workstations and GPU servers for startups, university labs and enterprise research teams.
StanfordMITUC BerkeleyCarnegie MellonGeorgia TechLockheed MartinBoeingApple
Start Here

Find the right server.

Who shares it, how jobs reach it and what it runs: see the memory estimate, the assumptions behind it and every server and rack build that holds it.

1

How do you want to start?

Two ways in, both ending at a system you can price.
Not sure? Ask an engineer ›

2

Tell us how it will be used.

Who shares it, then what it runs. Your answers go to the engineer with your request, and the estimate updates as you go.

00 · HOW WILL IT BE SHARED?
Who will use it
How work reaches it
Where it will live
01 · WHAT WILL IT RUN?
02 · PICK YOUR MODEL
03 · WORKLOAD
04 · PRECISION
05 · ONE CARD OR SEVERAL?
ESTIMATED GPU MEMORY
≈ 140 GB
OpenAI · 117B MoE · 5B active

117GB of weights at FP8, plus 20% for KV cache and overhead. An estimate: it assumes a short context and batch 1. Long contexts and bigger batches need more. MoE: all 117B of weights stay resident; 5B active per token is what makes it fast once loaded.
Digital Storm workstation
Starting point
Server Pro
AMD EPYC · 2× RTX PRO 6000
$75,779
  • gpt-oss 120B holds across 2 cards. ≈140GB estimated for inference, inside 192GB installed, 96GB per card. Memory is per card, so spanning them needs a runtime that supports it; we confirm that for your stack.
  • Room to grow. Server Pro runs two or four cards on the same EPYC platform.
  • Server memory. EPYC 9355P with 384GB DDR5 ECC for datasets, checkpoints and several users.

Where to save: a Rack Pro with 2× RTX PRO 6000 holds this too, from $54,069.

View systems
Your pick
3

Servers to consider.

Every GPU server and rack build we sell, sorted by price. The lowest-cost one that holds your estimate is marked. Customize and buy any of them online, or ask for a quote and an engineer confirms the details.
4 builds · $75,779 to $167,561 · sorted by price1–3 of 4
AMD EPYC
Server Pro
2× RTX PRO 6000 · 96GB
Server Pro GPU server, AMD EPYC with 2× RTX PRO 6000 · 96GB
EPYC 9355P · 32 cores
2× RTX PRO 6000 · 96GB
384GB DDR5 ECC
Rackmount · Ubuntu, CUDA, cuDNN
Starting at$75,779
Ships in an estimated 20 to 25 business daysLifetime support
AMD EPYC
Server Pro
2× H200 NVL · 141GB
Server Pro GPU server, AMD EPYC with 2× H200 NVL · 141GB
EPYC 9135 · 16 cores
2× H200 NVL · 141GB
384GB DDR5 ECC
Rackmount · Ubuntu, CUDA, cuDNN
Starting at$95,575
Ships in an estimated 20 to 25 business daysLifetime support
AMD EPYC
Server Pro
4× RTX PRO 6000 · 96GB
Server Pro GPU server, AMD EPYC with 4× RTX PRO 6000 · 96GB
EPYC 9135 · 16 cores
4× RTX PRO 6000 · 96GB
384GB DDR5 ECC
Rackmount · Ubuntu, CUDA, cuDNN
Starting at$96,884
Ships in an estimated 20 to 25 business daysLifetime support
AMD EPYC
Server Pro
4× H200 NVL · 141GB
Server Pro GPU server, AMD EPYC with 4× H200 NVL · 141GB
EPYC 9355P · 32 cores
4× H200 NVL · 141GB
384GB DDR5 ECC
Rackmount · Ubuntu, CUDA, cuDNN
Starting at$167,561
Ships in an estimated 20 to 25 business daysLifetime support
Found a better price from Dell, HP or another builder?Send us a written quote for an equivalent system. If it is lower, we will match it, with our 72-hour burn-in, our support and an engineer on your build still included.Equivalent means the same processor, graphics card, memory, storage, power supply class and warranty length. The quote must be in writing, dated within the last 30 days, from an authorized seller, and sent before you order. Not for used, open-box or marketplace listings, or bundles with free extras. One match per order.Send the quote
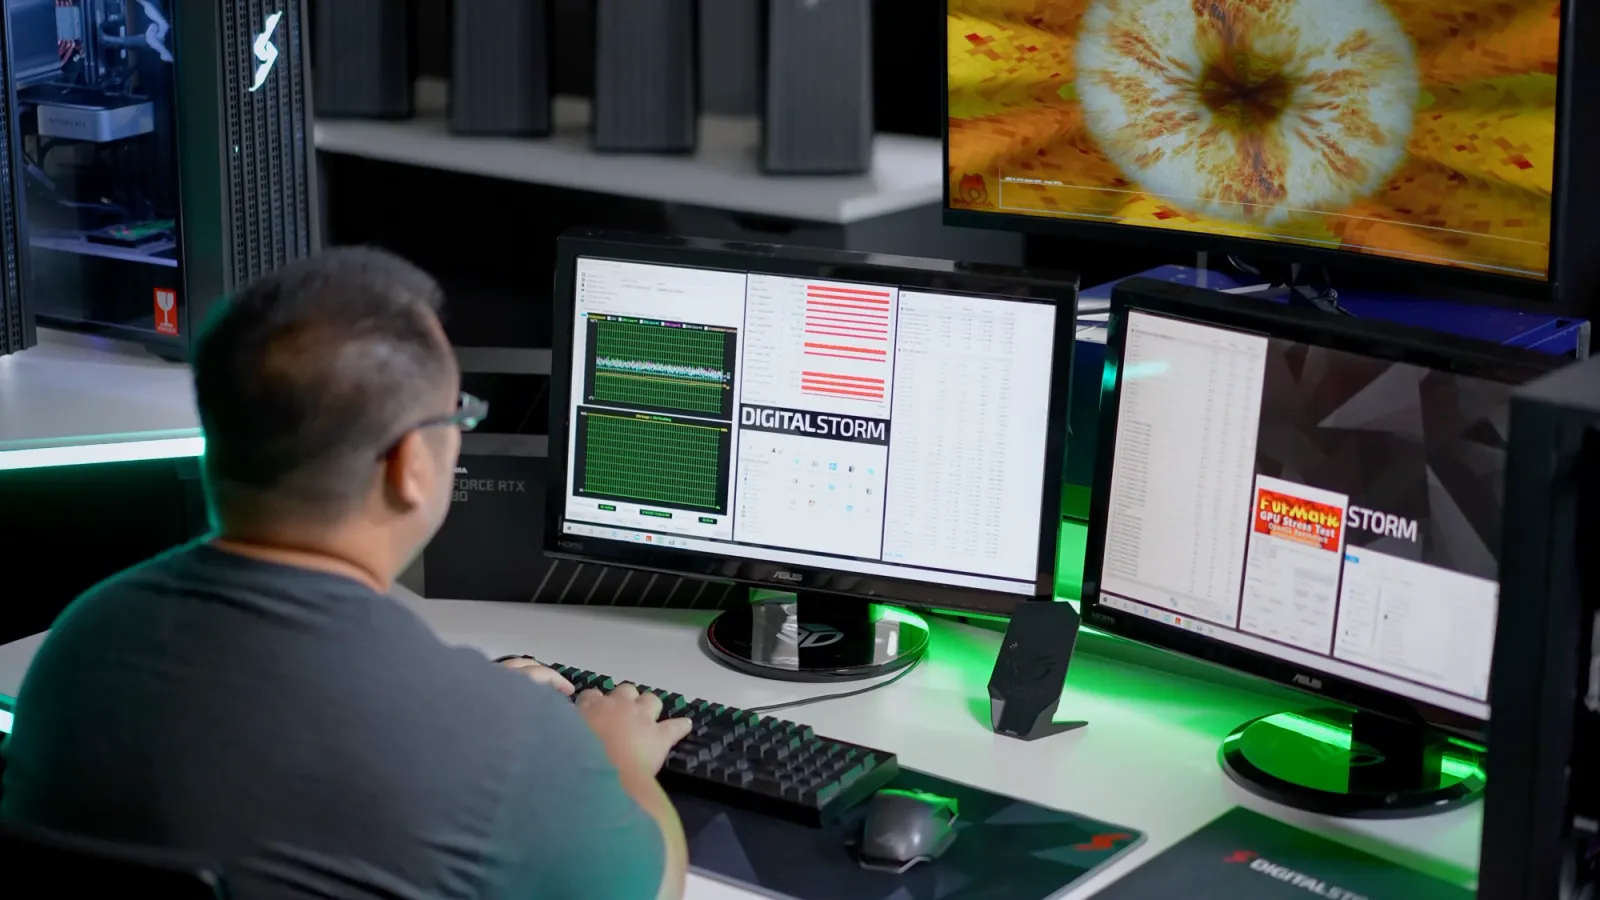
Digital Storm systems engineer beside a workstation running a machine learning dashboard

Your systems engineer

Talk through how your team will share it.

Talk through who will use it, how jobs reach it and what it has to hold. You get the configuration we recommend, and where a smaller machine would serve you just as well.

Talk to an engineerNo obligation · pricing in one business day

Published speed for the cards in these servers.

The RTX PRO 6000 is the card in most of these builds. Memory decides how much context one card holds on a large model; the right-hand panel shows what each server holds.

Large models on one card, by context length
Generation speed in tokens per second, llama.cpp, GGUF. Context is what the model reads at once: a long document, a codebase, a chat history. Hatched: the card could not hold that context in these runs.
tok/s at4k16k32k64k128kgpt-oss 120B · MXFP4RTX PRO 6000 · 96GB21018216213310048GB cards and smallerDoes not fit: the MXFP4 file is 63.4 GB.Llama 3.3 70B · 4-bitRTX PRO 6000 · 96GB3228262217RTX PRO 5000 · 48GB2422Did not fitDid not fitDid not fitRTX PRO 4500 · 32GB
RTX PRO 4000 · 24GB
Does not fit: the Q4_K_M file alone is 42.5 GB.
Hardware Corner’s runs on one 600 W RTX PRO 6000 and one RTX PRO 5000 48GB, published March 2026 (6000, 5000). OpenAI lists gpt-oss 120B at 5.1B active of 117B parameters, so it generates faster than the dense 70B. Reading the prompt slows as it grows: on the RTX PRO 6000, gpt-oss 120B reads 4,579 tokens per second at 4k and 1,290 at 128k.
What each server holds
GPU memory across the cards in each Server Pro build, with its starting price.
2× RTX PRO 6000 · 96 GB eachServer Pro, $75,779192 GB
2× H200 NVL · 141 GB eachServer Pro, $95,575282 GB
4× RTX PRO 6000 · 96 GB eachServer Pro, $96,884384 GB
4× H200 NVL · 141 GB eachServer Pro, $167,561564 GB
Every row is a build we sell today, priced from the configurator. Memory is per card: a model larger than one card is split across cards, and the runtime has to support that, which we confirm for your stack.

Why research teams choose Digital Storm.

Cloud GPUs fit short bursts and work that must scale within minutes. A large OEM fits when procurement mandates a fleet vendor. Here is the honest comparison for a server that stays busy.

Digital Storm vs. the alternatives, for teams buying a GPU server
CapabilityDigital StormThat’s usCloud GPUsLarge OEM
Cost structureOngoing usagePurchase price
Your data and weights stay in-housePer contract✓
Sized to how your team shares itInstance sizesCatalog options
Two to four RTX PRO 6000 or H200 NVL✓✓
72-hour full-load burn-in before shippingn/aFactory QA
An engineer on your quote, lifetime supportSupport plansContracts
Formal quotes and purchase orders✓✓
More GPUs within minutes✓–

A shared server is sized for everyone on it.

Serving a team and training a model ask different things of a server. Here is how we tell them apart.
Data-science session on a Digital Storm workstation
Serving scales with traffic
Fitting the weights is the first check. How many people call the model at once, and how long their prompts run, decide the cards. We size for the traffic you expect, not the checkpoint.
A Digital Storm engineer at a QA bench
Training holds more than the weights
Full training keeps weights, gradients and optimizer states in memory, roughly 16 bytes a parameter in mixed precision. We size training on that figure, and serving on the weights and cache.
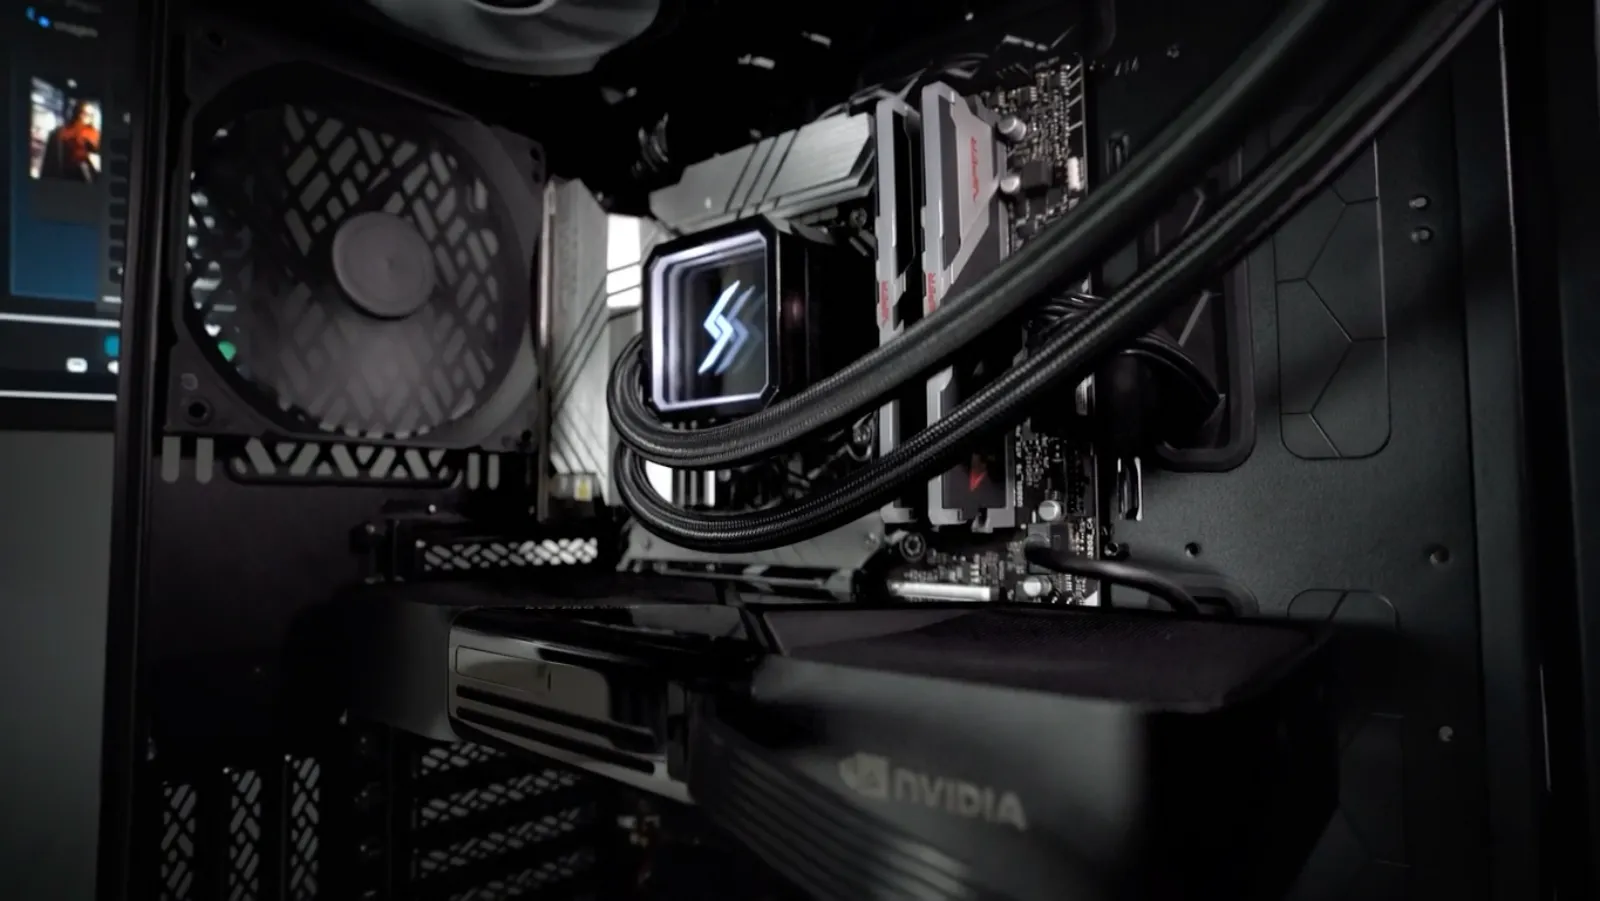
Inside a Digital Storm system with NVIDIA RTX PRO GPUs
Memory is per card
Two cards hold two separate memories. A model larger than one card is split across them, so we confirm your runtime supports that before we quote, or size the job onto one larger card, like the H200 NVL.

Ordering through purchasing.

Large server orders usually go through a purchasing office, a prime contractor or a reseller. Here is how that works with us.

Purchase orders and terms

Send the PO against our quote, with your tax-exemption certificate if your organization has one. Send purchase orders to Andrew Bain, [email protected]. Net 30 terms, subject to approval.

Through a prime contractor or reseller

Ordering through a prime contractor or a reseller? We quote to them, for the configuration your engineer sized with you.

Vendor paperwork

We send a W-9, complete supplier portal forms and are registered on SAM.gov.

Itemized quotes

Quotes are valid for 30 days. Each one is itemized, so purchasing sees every part, and lists the warranty terms.

Matching an earlier order

Give us the order or quote number and how many you need. We price the same configuration and tell you which parts have changed since.

Academic and multi-system pricing

A 5% academic discount for universities and academic research organizations, or 5% off three or more identical systems. The two do not combine.

How purchasing works with us →

Get a server sized for the whole team.

Tell us what you run. A systems engineer replies with pricing in one business day, servers included. No obligation.

Purchase orders welcomeTax-exempt for eligible organizationsUniversity and government procurement

What do you need?

No obligationReviewed by an engineerQuotes valid for 30 days